
This fork adds two draft-model-free speculative decoding methods to the Hugging Face Transformers generate loop:
- Suffix decoding. An online compressed suffix tree over the prompt and accepted tokens proposes a draft continuation by matching the recent token tail; optional per-request and cross-request trees with FIFO eviction.
- Tree speculative decoding. Drafts a whole tree of candidate continuations from the same suffix tree and verifies it in one forward pass using a 4D tree attention mask and depth-based position ids, then keeps the longest accepted branch.
Both keep greedy outputs unchanged: drafts are always verified by the target model.
Qwen3-8B on one H100, bf16, batch size 1, greedy, up to 384 new tokens, 30 prompts per task, all methods run back to
back per prompt in rotated order. Geometric-mean speedup over autoregressive decoding, recomputed from the raw records
in bench_tree_spec/results/qwen3-8b-h100-v3.json:
| Task | Prompt lookup | Suffix | Tree |
|---|---|---|---|
| Code editing (CanItEdit) | 3.90× | 6.64× | 9.04× |
| HumanEval | 1.69× | 1.85× | 1.93× |
| GSM8K | 1.41× | 1.43× | 1.57× |
| Chat (MT-Bench) | 1.11× | 1.15× | 1.13× |
| All | 1.79× | 2.12× | 2.36× |
Tree vs. suffix, paired per prompt: 1.11× (95% bootstrap CI 1.08–1.15). Method, ablations and profiling:
bench_tree_spec/RESULTS.md. The original course evaluation (L40S, six workloads, up to
1.74× for suffix decoding) is in stormckey/sd-bench.
from transformers import AutoModelForCausalLM, AutoTokenizer
from transformers.generation import SuffixDecodingCache

tok = AutoTokenizer.from_pretrained("Qwen/Qwen3-8B")
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-8B", torch_dtype="auto", device_map="auto")
inputs = tok("Translate to English: Bonjour tout le monde.", return_tensors="pt").to(model.device)

# Suffix decoding (linear drafts); the cache is optional and shares trees across requests.
out = model.generate(**inputs, max_new_tokens=256, do_sample=False,
                     suffix_decoding_num_tokens=10,
                     suffix_decoding_cache=SuffixDecodingCache(max_depth=64, max_cached_requests=100))

# Tree speculative decoding with the settings used for the results above.
out = model.generate(**inputs, max_new_tokens=256, do_sample=False,
                     tree_spec_decoding_num_tokens=128, tree_spec_decoding_branch_factor=8,
                     tree_spec_decoding_min_prob=0.02,
                     tree_spec_decoding_max_spec_factor=1e9, tree_spec_decoding_max_spec_offset=1e9)
Both snippets were smoke-tested on a tiny GPT-2: outputs match plain greedy generate.
The tree verifier first written by the team cropped the KV cache to the first n flattened draft nodes, which is only
correct when the accepted branch is the first one in flattened order; otherwise rejected tokens' KV stayed in the cache
and corrupted later steps. It now moves the accepted path's KV next to the prefix before cropping, and in float32 every
method reproduces greedy decoding exactly (tests/generation/test_candidate_generator.py). Lifting the old draft-size
cap was the main speed win: a Qwen3-8B forward on H100 costs about the same for 1 or 129 query tokens.
CMU 15-642 (Spring 2026) team project by Chenhao Gao, Yuchen Zhou and Zihao Du. Chenhao wrote the suffix tree,
SuffixDecodingCandidateGenerator, generation integration and cross-request cache (April 2026), and the tree-verifier
fix, tests and H100 benchmarks (September 2026). The initial tree-spec branch and source-mode selector are team work;
Git history keeps each author's commits.
The remainder of this document is the upstream Hugging Face Transformers README.






English | 简体中文 | 繁體中文 | 한국어 | Español | 日本語 | हिन्दी | Русский | Português | తెలుగు | Français | Deutsch | Italiano | Tiếng Việt | العربية | اردو | বাংলা |

Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be simple, customizable, and efficient.
There are over 1M+ Transformers model checkpoints on the Hugging Face Hub you can use.
Explore the Hub today to find a model and use Transformers to help you get started right away.
Transformers works with Python 3.10+, and PyTorch 2.4+.
Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.
# venv
python -m venv .my-env
source .my-env/bin/activate
# uv
uv venv .my-env
source .my-env/bin/activate
Install Transformers in your virtual environment.
# pip
pip install "transformers[torch]"

# uv
uv pip install "transformers[torch]"
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.
git clone https://github.com/huggingface/transformers.git
cd transformers

# pip
pip install '.[torch]'

# uv
uv pip install '.[torch]'Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
from transformers import pipeline

pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.
Tip
You can also chat with a model directly from the command line, as long as transformers serve is running.
transformers chat Qwen/Qwen2.5-0.5B-Instructimport torch
from transformers import pipeline
chat = [
{"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
{"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]
pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])Expand the examples below to see how Pipeline works for different modalities and tasks.
Automatic speech recognition
from transformers import pipeline

pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
Image classification
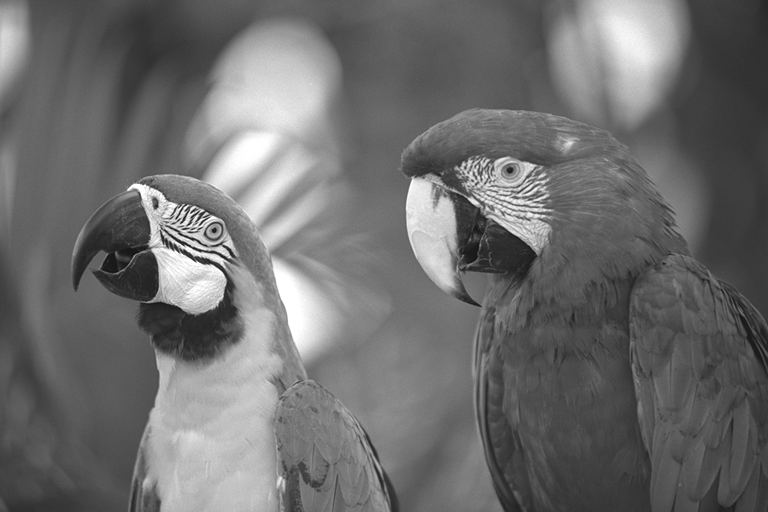
from transformers import pipeline

pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
 {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
  'score': 0.0016551691805943847},
 {'label': 'lorikeet', 'score': 0.00018523589824326336},
 {'label': 'African grey, African gray, Psittacus erithacus',
  'score': 7.85409429227002e-05},
 {'label': 'quail', 'score': 5.502637941390276e-05}]
Visual question answering
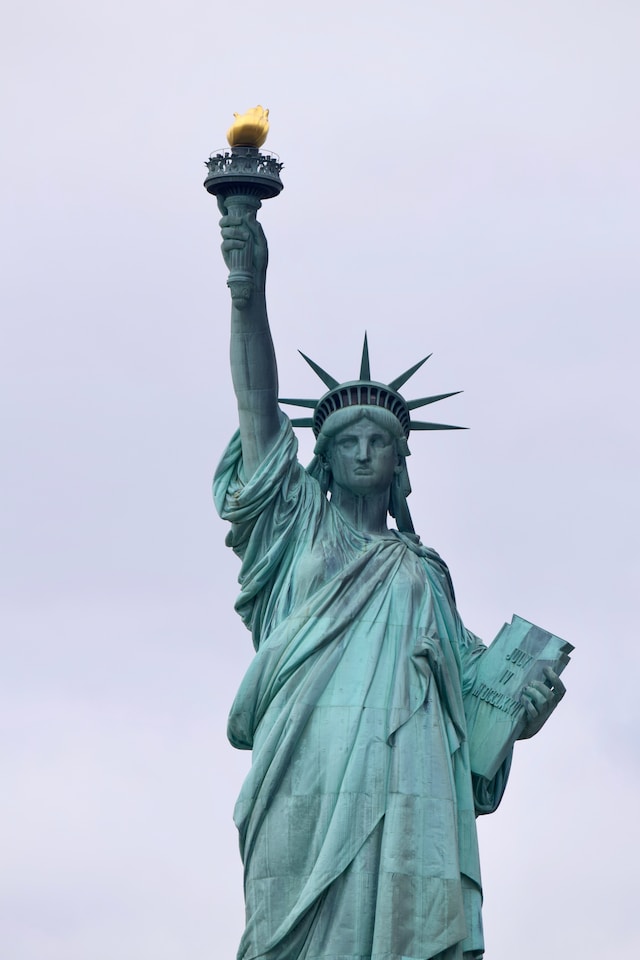
from transformers import pipeline

pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]-
Easy-to-use state-of-the-art models:
- High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
- Low barrier to entry for researchers, engineers, and developers.
- Few user-facing abstractions with just three classes to learn.
- A unified API for using all our pretrained models.
-
Lower compute costs, smaller carbon footprint:
- Share trained models instead of training from scratch.
- Reduce compute time and production costs.
- Dozens of model architectures with 1M+ pretrained checkpoints across all modalities.
-
Choose the right framework for every part of a model's lifetime:
- Train state-of-the-art models in 3 lines of code.
- Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
- Pick the right framework for training, evaluation, and production.
-
Easily customize a model or an example to your needs:
- We provide examples for each architecture to reproduce the results published by its original authors.
- Model internals are exposed as consistently as possible.
- Model files can be used independently of the library for quick experiments.

- This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.
- The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like Accelerate.
- The example scripts are only examples. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work.
Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone else to build their dream projects.
In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the community with the awesome-transformers page which lists 100 incredible projects built with Transformers.
If you own or use a project that you believe should be part of the list, please open a PR to add it!
You can test most of our models directly on their Hub model pages.
Expand each modality below to see a few example models for various use cases.
Audio
Computer vision
- Automatic mask generation with SAM
- Depth estimation with DepthPro
- Image classification with DINO v2
- Keypoint detection with SuperPoint
- Keypoint matching with SuperGlue
- Object detection with RT-DETRv2
- Pose Estimation with VitPose
- Universal segmentation with OneFormer
- Video classification with VideoMAE
Multimodal
- Audio or text to text with Voxtral, Audio Flamingo
- Document question answering with LayoutLMv3
- Image or text to text with Qwen-VL
- Image captioning BLIP-2
- OCR-based document understanding with GOT-OCR2
- Table question answering with TAPAS
- Unified multimodal understanding and generation with Emu3
- Vision to text with Llava-OneVision
- Visual question answering with Llava
- Visual referring expression segmentation with Kosmos-2
NLP
We now have a paper you can cite for the 🤗 Transformers library:
@inproceedings{wolf-etal-2020-transformers,
    title = "Transformers: State-of-the-Art Natural Language Processing",
    author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://www.aclweb.org/anthology/2020.emnlp-demos.6",
    pages = "38--45"
}