


A purple-team of AI agents that audits code security and proves findings by execution — not by opinion.
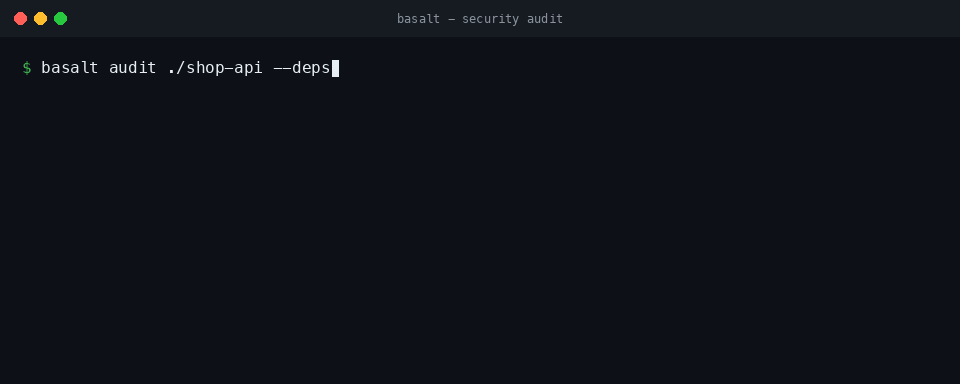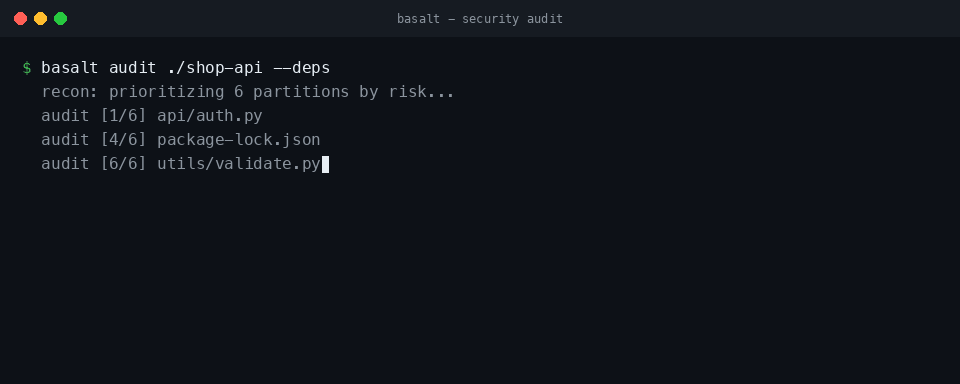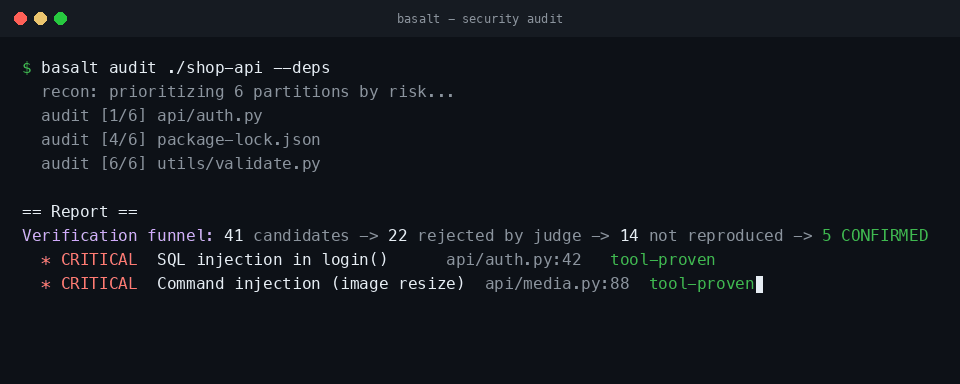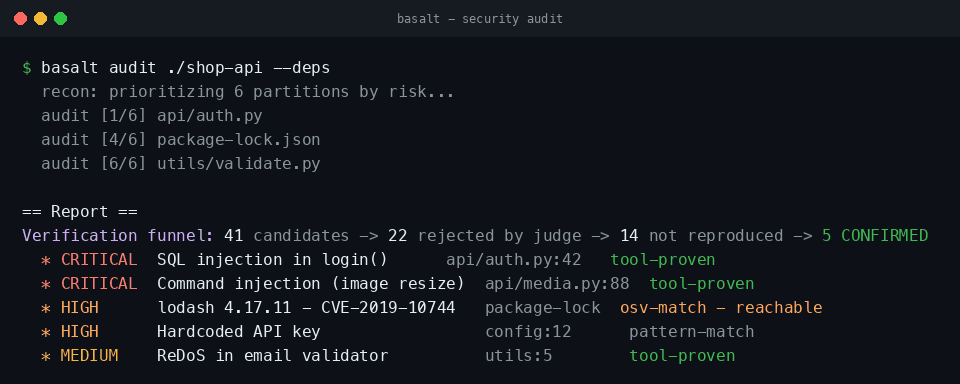
Most "AI security scanners" hand you a list of maybe-bugs a model thinks it found. Basalt is different: a finding is only confirmed when its proof-of-concept is reproduced by execution in a clean, isolated sandbox (or matched against an authoritative vulnerability database). What you get is a short list of things that actually reproduce — with the evidence.
recon → red (find × N) → purple (verify) → EXECUTION in sandbox → blue (patch) → grader
        └ consensus voting          └ skeptical judge      └ sentinel must fire
Screening, not a substitute for a professional manual audit of code holding real funds. Based on the 2024–2026 evidence (Google Big Sleep, Anthropic's defending-code harness, LLM-SmartAudit): what actually cuts false positives is reproducing the PoC by execution, not model-vs-model debate.
- Execution-verified findings. A candidate is
confirmedonly if its PoC fires theBASALT-POC-TRIGGEREDsentinel in a network-less Docker sandbox. Every finding carries honest provenance:tool-proven,osv-match,pattern-match, ormodel-asserted. - A verification funnel in every report — "N candidates → rejected by judge → not reproduced → confirmed" — so you can see the filtering, not just the conclusions.
- Deterministic scanners that just work (stable): dependency N-day vs
OSV.dev, Go reachability via
govulncheck, and hardcoded-secret detection (never stores the secret value). - Multi-language: Python, Go, TypeScript/JS, Rust, Solidity, generic.
- Built for CI: severity-gated exit codes, PR-only
--changedaudits, cost--dry-run, and reports as Markdown/JSON/HTML + a professional Word/PDF audit document with an evidence bundle. - Pluggable models: Claude (subscription CLI or API), any OpenAI-compatible gateway, or local Ollama — per role, with fallback chains.
⚠️ Maturity. The deterministic scanners (N-day, reachability, secrets) are stable. The LLM discovery path (finding logic bugs via the red agent) is beta — verified-by-execution, but coverage and precision are still maturing. See Known limitations.
pipx install "basalt-scan[claude,doc]"   # recommended — installs the `basalt` command
# or: pip install "basalt-scan[claude,doc]"
basalt init                              # writes config/basalt.yaml
The distribution is basalt-scan; the command and import package are
basalt. Extras: claude (Anthropic SDK), doc (Word/PDF reports),
mcp (MCP server), sandbox (Docker SDK).
Docker is required for execution-based verification. govulncheck is optional
(Go reachability). The Word/PDF report uses WeasyPrint, which needs system libs
(pango, cairo).
From source (development)
git clone https://github.com/Arkessiah/Basalt && cd Basalt
python -m venv .venv && source .venv/bin/activate
pip install -e ".[dev,claude,doc]"basalt doctor # providers + Docker + govulncheck health
basalt audit ./repo --deps --patch --report out.md # full audit
basalt audit ./repo --dry-run # estimate cost (no model calls)
basalt audit ./repo --changed --base main # PRs: only changed files
basalt audit ./repo --fail-on high # CI: non-zero exit on high+ findings
basalt deps ./repo --reachability # dependency N-day (OSV) + Go reachability
basalt secrets ./repo # hardcoded secrets (cross-language)
basalt report --format html -o report.html # markdown | json | html
basalt doc ./repo -o audit # Word + PDF proof document
basalt bundle ./repo -o evidence.zip # report + PoCs + logs + hash
basalt gate --fail-on high # CI gate over the findings store
basalt mcp-serve # MCP server: drive audits from an MCP clientReport/document language is English by default; set lang: es in the config
for Spanish (extensible to more languages).
- Recon maps the attack surface and prioritizes partitions by risk.
- Red (find × N) independent agents look for vulnerabilities and produce a runnable PoC; consensus voting filters hallucinations.
- Purple (verify) is a skeptical judge that demands a credible PoC.
- Execution reproduces the PoC in a clean, isolated Docker sandbox — the
finding is
confirmedonly if the exploit actually fires. - Blue (patch) + Grader propose a minimal fix and grade it by execution: green build, closed PoC, no test regressions.
Untrusted target content is spotlighted and secret-redacted before it reaches any model, and the model agents never invoke tools directly — the deterministic orchestrator mediates all execution.
Layout: providers/ models · agents/ roles · orchestrator.py the loop ·
sandbox/ isolated execution · targets/ language adapters · deps.py /
reachability.py / secrets_scan.py deterministic scanners · report.py /
audit_doc.py output · role prompts in prompts/*.md.
- LLM discovery is beta — execution-verified, but not yet a replacement for a thorough manual review; the deterministic scanners are the solid part today.
- Reachability is Go-only (
govulncheck); other ecosystems reportunknown, so an N-day may be present but not exercised. - Solidity PoC reproduction needs
forge-stdavailable in the target project. - Compiled-language PoCs must be self-contained (the sandbox has no network).
Basalt is a defensive tool: audit code/infrastructure you own or are
authorized to test. It executes PoCs and target code inside an isolated
sandbox. See SECURITY.md for authorized-use and responsible
disclosure. You are responsible for how you use it.
See CONTRIBUTING.md. CI runs ruff + pytest on Python
3.11/3.12.
MIT — © 2026 Arkessiah. See LICENSE.